Train an AI agent to scrape and extract structured data from any website. Turn web pages into spreadsheets, APIs, or live data pipelines without writing a single line of code.
A work email gets you team features and faster support.

Build and manage web scrapers to extract and structure the data you need from any website with built in bot evasion, automatic retries, and proxy management.

Automations and workflows to scrape thousands of websites automatically transforming an entire website in a live dataset.

Web scraping that automatically adapts to website changes (no more broken code) keeping your data accurate, even when websites change.

Skip the proxy configurations, and rotating IPs. Reliably extract data from 98% of websites including JavaScript-heavy, and dynamic content.

Our AI blends in perfectly with human traffic. No more blocked requests or rate limits with an AI web scraper that navigates sites naturally.

Transform any website into a REST API endpoint or integrate with 7,000+ apps via Zapier, Make, and Pabbly.
Our team handles complex, custom, or high-volume web scraping projects. Get expert setup, fully managed delivery, or enterprise-scale infrastructure.
Book a free consultation →We offer set up services, full service data management, fully managed web scraping, and more depending on your needs.
Extract, and monitor data reliably with endless scale from thousands of websites on one web scraping platform.
Our data extraction services team designs, builds, and manages the exact operational data workflows your business requires.
Instantly scrape from webpage into a structured table with our AI web scraper.
Extract, and scrape thousands of webpages and websites with workflows and automations.
Monitor for website changes to keep your data up to date and accurate.
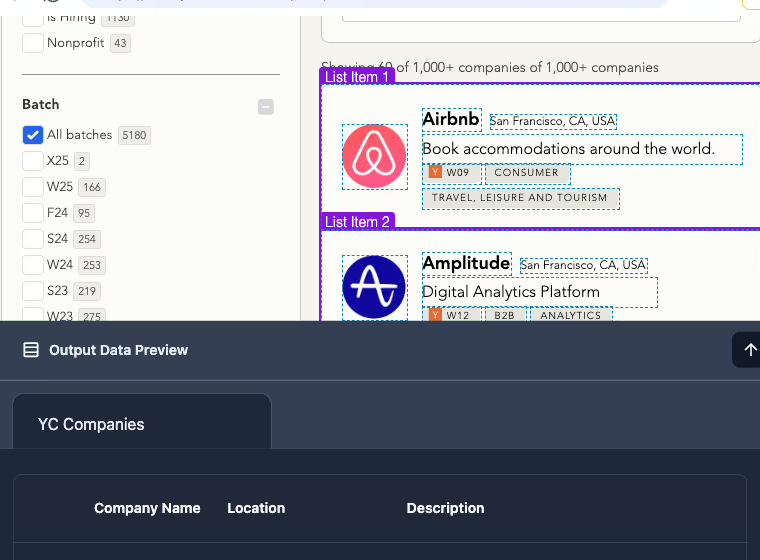
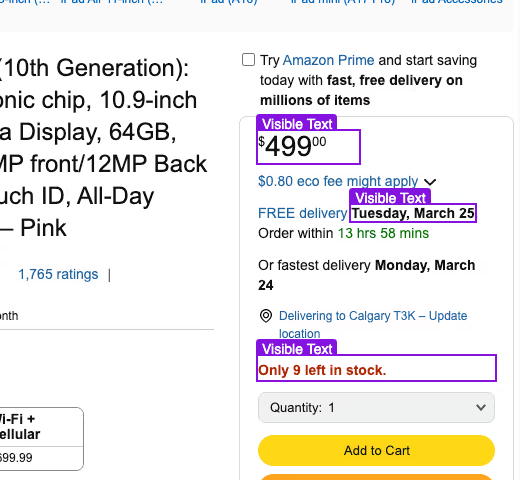
Capture and structure the exact data you want to scrape or extract.
Scrape dynamic data including toggling filters, fill out forms, complete search fields and more.
Transform entire websites into structured datasets with workflows and automations.
Automatically capture screenshots and monitor for visual changes on any web page.
Capture visual data and website changes that traditional data extraction tools can't detect.
Set up scheduled monitoring and get alerted when visual changes occur and what has changed.
Companies rely on Browse AI to transform web content into business critical datasets at scale. Our AI-powered web scraping and data extraction platform delivers unmatched reliability, performance, and accuracy.
Businesses save up to 70% by switching from in-house solutions to our web scraping platform.
No more broken scrapers and scripts, and ongoing headache.
Our enterprise web scraping infrastructure handles millions of concurrent data extractions across thousands of websites simultaneously.
Built for the most demanding operational data requirements at unlimited scale.

Our quality assurance processes and AI-powered monitoring ensure the highest data quality standards for business-critical decisions.
We work with you to establish data quality SLAs and procedures.
Scrape websites and extract website data to build datasets that matter to your business.

Scrape, extract, and monitor your competitor's website, reviews, listings, and more. Build a custom competitive intelligence databases that update automatically.

Extract and monitor prices and products across hundreds of sources. Perfect for competitive monitoring, tracking MAP compliance, brand monitoring, and more.

Extract contact information and business data from professional directories, industry websites, and business platforms.

Scrape, extract, and monitor market trends, industry reports, and business intelligence data from multiple sources. Build ongoing market monitoring systems that track changes in real-time.

Monitor supplier websites, pricing changes, and inventory levels across your entire supply chain.

Extract web data into live structured datasets specific to your business needs. Perfect for ongoing monitoring of regulations, compliance, or niche market data.
Discover why entrepreneurs and businesses trust Browse AI to extract web data, automate workflows, and build real-time data pipelines effortlessly.
Everything is no-code, so as a non-technical person I felt empowered to be able to do anything I needed with a bit of learning and testing.
 Chris C.
It's so easy to follow along and teach it to do the work for you. Even a complete beginner can build a working tool super quickly. Building these used to take hours now it takes minutes with Browse AI.
 Erin J.
Browse AI is fabulous and has saved us many many days of development time allowing us to focus on the core features of our platform rather than data capture.
 Jonathan G.
It's a very simply and reliable tool to extract data from web. In just minutes I solved my problems with Browse AI after spending hours with other tools.
 Mauricio A.
Browse AI allows you to scrape websites with no code and is so simple and easy to use. You can scrape absolutely any website using this without any hustle and download the results too.
 Rukaiya B.
How easy it is to setup a scraper! just set and forget with the monitor. fastest customer support I've witnessed. They even helped me with a Robot I set up which had to scrape data behind some firewall.
 Yassine B.
Scrape data from any website with the best web scraping tool in the market that businesses rely on.
Extract data from thousands of web pages into a live dataset. Train a robot to extract the data you want and then scale it across other web pages using workflows, and automations.
Automatic retries, intelligent rate limiting, proxy management, and error recovery to ensure consistent extraction making it scalable to extract reliably from millions of pages.
Scrape data behind a login, search query, drop downs and more. Train your robot to fill out forms, toggle drop downs, and login to scrape the data you need.
Integrate your scraped dataset into your existing tools, apps, and business automations via API, Webhooks, Zapier, Make, Google Sheet, and more.
Built to extract data from virtually any website, including those with CAPTCHAs, geographic restrictions, pagination, infinite scrolling, and dynamic content.
Build your web scrapers with custom parameters including search terms, date ranges, or geo locations.
Get started in minutes and start scraping thousands of webpages across multiple sources.
Get started nowSync your scraped data to Google Sheets, Zapier, Make.com, Airtable, and more. Learn more about integrations.
All integrations


Some extractions are common enough that we have already built the robot. Pick one, point it at a URL, and run it.
Pull a complete list of every page on a site, ready to use as the input for a bulk run.
Try this robot freeCapture a page's raw HTML and a screenshot together, for auditing or archiving.
Try this robot freeExtract all readable text from a page alongside a full-page screenshot.
Try this robot free
Train a robot to scroll, click through drop downs, toggle filters, and fill out forms, then extract what appears.

Follow numbered pages, load-more buttons, and infinite scroll to the end of a list.
Give a robot a variable at run time, such as a search term or a location, and get results back for each one.
Extract the version of a page that a visitor in a specific country would see.
Provide credentials or session cookies, encrypted and used only when your robot runs.
Robots mimic human behavior and handle rate limiting, IP rotation, and standard CAPTCHAs, including Cloudflare.
Point it at the page and capture what you need, whether that is structured records, raw text, links, or a picture of the page itself.

Pull headings, body copy, product descriptions, prices, or any single element on a page. Train a robot once and it captures the same fields across thousands of pages.

Capture the URL and file name of every document linked on a page, then fetch them with your own tooling. Robots extract the links, they do not download the files themselves.
Robots return links, not the files. How file capture works →
Collect every link on a page or map an entire site's URL structure, then feed that list straight into another robot as its input.
Capture repeating elements such as product grids, search results, or directory listings, and get them back as clean, structured rows.

Extract image links and alt text alongside the records they belong to. Need the visual itself rather than the link? Capture a screenshot instead.
Robots return image URLs, not image files. How image capture works →

Take a full-page or partial screenshot, or capture the underlying HTML, for archiving, auditing, or change comparison.
One robot captures one page. Chain them together and you can turn a whole site into a single unified dataset that stays up to date on its own.
Start with a robot that collects the URLs you care about, whether that is a sitemap, a category page, or a set of search results.
Feed that list into a second robot and run it across up to 500,000 URLs at once. Every page with the same structure returns the same fields.
Schedule the run, and set up change detection so you are alerted when the underlying data moves rather than finding out later.
The result behaves like a database you own: export it as CSV or JSON, sync it to Google Sheets or Airtable, query it through the REST API, or push it into any of 7,000+ connected tools.
Browse AI is the easiest and most reliable way to scrape or extract data from any website. Give it a URL and AI builds the extraction for you, with no code. You can train a robot in minutes to:
To get started, enter the URL where you want to scrape the data, and review the data structure the AI suggests. It will then extract the data you want in a structured format.
The robot mimics human behavior to reliably extract data even from complex websites with login requirements, CAPTCHAs, or dynamic content. It's also instantly trained to avoid bot detection (including Cloudflare), so that it can reliably scrape and extract the data you need.
Once trained, your web scraping robot can extract data on demand or be scheduled to run automatically.
You can scrape and extract any website data using Browse AI. Our web scraping tool has three extraction methods to scrape websites:
All of the above can be created using our no code web scraping platform. This allows you to extract exactly what you need, whether it's structured datasets, specific information, or visual elements.
Behind our no code interface, Browse AI's core is designed for reliability and scale. Unlike traditional web scraping solutions and tools that often break, or fail at avoiding bot detection (especially at scale), our platform was built for reliable and high scale data extraction and web scraping.
Some of these features include:
Absolutely! Browse AI is designed so anyone can scrape or extract data (no technical background needed).
Our no-code web scraping builder creates web scraping and extraction robots in minutes without a single line of code. Point it at a URL, and all you need to do is review and approve the data the AI suggests.
Browse AI automatically organizes and stores the data you've scraped and/or extracted into structured tables that you can view in your dashboard.
You can:
You can also scale the data you've scraped by:
If you're looking for advanced data post processing, high scale data extractions or have custom needs be sure to reach out to our sales team to learn about our managed services options.
Yes, Browse AI can extract data from sites that require login (assuming of course that you own the data, and you have permission to do so).
When training your scraping robot, you can securely provide your login credentials or use session cookies. Browse AI encrypts this information and uses it only when running your robot.
This feature is perfect for extracting data from member areas, professional platforms, or any site requiring authentication.
Browse AI offers a free pricing tier so that you can validate that our data extraction capabilities meet your needs, or you can use us as a free web scraping tool for small extractions.
All plans (including our free plan!) come with full platform access meaning that we don't limit features or capabilities of our free plan within the product.
As part of the free plan you'll have access to:
There is no credit card required to sign up. Paid tier plans provide you with additional credits and websites as you scale. Our Premium plan offers high scaled enterprise web scraping, as well as customized web scraping services.
Browse AI's AI-powered engine adapts to website changes so your extracted data remains accurate. This is where traditional scrapers (and python based solutions) tend to fail.
When a website changes, our machine learning and AI core adapt the scraping code to keep your data accurate. You can also set up custom alerts and notifications to these changes. The robot is designed to continue working even when websites update their layouts or structures.
If a website significantly changes its structure (or the data you want or how you want it structured might change) and the AI is unable to adapt the code, you can also retrain your robot while preserving your workflows and integrations.
Yes we offer data processing either through our integration and export options, or as a full service option for our Premium customers.
Browse AI's core product focus is on the extraction, scraping, and monitoring of web data. Once you have the data you need, there are several ways to process your data.
Within these tools you can transform, filter, and further structure the data based on your needs. You can also create automations and workflows to connect the data with your internal tools and apps.
For our Premium customers we offer data processing and management as part of our custom managed services options. If you want to learn more talk to our sales team.
With Browse AI, you can turn any website into an API. Our REST API gives you:
We also offer the ability for you to integrate with the data you scrape via Webhook. For detailed capabilities and implementation examples, you can refer to our API documentation.
Browse AI is designed to reliably scrape, extract and monitor data from any website. At the core, it has features that are built to work around bot detection, Cloudflare detection, and CAPTCHA handling.
This includes a collection of features that are unlike traditional web scrapers or python script based solutions:
If you need to extract data behind a login, or on a site that requires authentication, Browse AI securely handles login credentials and session cookies. (Note that this sensitive information is encrypted and only used when running your robot.)
While Browse AI is really simple to get started and use, it's designed for scale and complexity. You can build a scraper in minutes for almost any simple data extraction.
However, if you're looking for complexity and scale we also offer a suite of features to make any data you need easy to scrape. These include:
For highly specialized or complex needs we also offer Premium services where we either fully manage our data extraction or scraping project, or we set things up for you. Reach out to our sales team to learn more.
Yes, Browse AI has helped thousands of businesses and enterprises scrape data. Some businesses scrape millions of rows of data with us daily as part of their core business operations.
A web content extractor is a tool that pulls text, images, links, and other page content out of a website and returns it as structured data. Browse AI works as a no-code website content extractor: point it at the page, review the content the AI suggests, and a robot captures it into rows you can export or send to another system on a schedule.
The terms are used interchangeably. A web extractor (or website extractor) pulls specific fields off a page, such as a price, a listing, or a job title, while web scraper is the broader term for automating that at scale. Browse AI does both: train a robot once on the fields you care about, then run it across thousands of pages on a schedule.
Web data extraction is the process of turning unstructured web pages into structured records: rows, columns, and fields you can query. Browse AI handles the whole web data extraction pipeline, from training the robot to running it on a schedule, adapting when the site changes, and delivering results to your spreadsheet, warehouse, or API.
Get started quickly with one of our most popular prebuilt robots. Each one is ready to run in minutes.